Search This Blog

Wednesday, 13 August 2014

Dynamic Host Configuration Protocol (DHCP)

We observed that Ethernet addresses are configured into the network adaptor by the manufacturer, and this process is managed in such a way to ensure that these addresses are globally unique. This is clearly a sufficient condition to ensure that any collection of hosts connected to a single Ethernet (including an extended LAN) will have unique addresses. Furthermore, uniqueness is all we ask of Ethernet addresses.

IP addresses, by contrast, not only must be unique on a given internetwork, but also must reflect the structure of the internetwork. They contain a network part and a host part, and the network part must be the same for all hosts on the same network. It is not possible for the IP address to be configured once into a host when it is manufactured, since that would imply that the manufacturer knew which hosts were going to end up on which networks, and it would mean that a host, once connected to one network, could never move to another. For this reason, IP addresses need to be reconfigurable.

Most host operating systems provide a way for a system administrator, or even a user, to manually configure the IP information needed by a host. However, there are some obvious drawbacks to such manual configuration.

It is simply a lot of work to configure all the hosts in a large network directly, especially when you consider that such hosts are not reachable over a network until they are configured. Even more importantly, the configuration process is very error-prone, since it is necessary to ensure that every host gets the correct network number and that no two hosts receive the same IP address. For these reasons, automated configuration methods are required. The primary method uses a protocol known as the Dynamic Host Configuration Protocol (DHCP).

DHCP relies on the existence of a DHCP server that is responsible for providing configuration information to hosts. There is at least one DHCP server for an administrative domain. At the simplest level, the DHCP server can function just as a centralized repository for host configuration information.

A more sophisticated use of DHCP saves the network admininstrator from even having to assign addresses to individual hosts. In this model, the DHCP server maintains a pool of available addresses that it hands out to hosts on demand. This considerably reduces the amount of configuration an administrator must do, since now it is only necessary to allocate a range of IP addresses (all with the same network number) to each network.
Since the goal of DHCP is to minimize the amount of manual configuration required for a host to function, it would rather defeat the purpose if each host had to be configured with the address of a DHCP server. Thus, the first problem faced by DHCP is that of server discovery.

To contact a DHCP server, a newly booted or attached host sends a DHCPDISCOVER message to a special IP address (255.255.255.255) that is an IP broadcast address. This means it will be received by all hosts and routers on that network. (Routers do not forward such packets onto other networks, preventing broadcast to the entire Internet.) In the simplest case, one of these nodes is the DHCP server for the network. The server would then reply to the host that generated the discovery message (all the other nodes would ignore it). However, it is not really desirable to require one DHCP server on every network because this still creates a potentially large number of servers that need to be correctly and consistently configured. Thus, DHCP uses theconcept of a relay agent. There is at least one relay agent on each network, and it is configured with just one piece of information: the IP address of the DHCP server. When a relay agent receives a DHCPDISCOVER message, it unicasts it to the DHCP server and awaits the response, which it will then send back to the requesting client. The process of relaying a message from a host to a remote DHCP server is shown


A DHCP relay agent receives a broadcast DHCPDISCOVER message from a host and sends a unicast DHCPDISCOVER message to the DHCP server.

Figure shows the format of a DHCP message. The message is actually sent using a protocol called UDP (the User Datagram Protocol) that runs over IP. 

DHCP PACKET FORMAT

DHCP is derived from an earlier protocol called BOOTP, and some of the packet fields are thus not strictly relevant to host configuration. When trying to obtain configuration information, the client puts its hardware address (e.g., its Ethernet address) in the chaddr field. The DHCP server replies by filling in the yiaddr (“your” IP address) field and sending it to the client. Other information such as the default router to be used by this client can be included in the options field.

Internet Protocol (IP)

Simple Internetworking

Internetwork refer to an arbitrary collection of networks interconnected to provide some sort of host to host packet delivery service.

An internetwork is often referred to as a “network of networks” because it is made up of lots of smaller networks. we see Ethernets, an FDDI ring, and a point-to-point link. Each of these is a single-technology network. The nodes that interconnect the networks are called routers. They are also sometimes called gateways, but since this term has several other connotations, we restrict our usage to router.

Internet Protocol

The Internet Protocol is the key tool used today to build scalable, heterogeneous internetworks. It was originally known as the Kahn-Cerf protocol after its inventors. One way to think of IP is that it runs on all the nodes (both hosts and routers) in a collection of networks and defines the infrastructure that allows these nodes and networks to function as a single logical internetwork.

Service Model

The IP service model can be thought of as having two parts: an addressing scheme, which provides a way to identify all hosts in the internetwork, and a datagram (connectionless) model of data delivery. This service model is sometimes called best effort because, although IP makes every effort to deliver datagrams, it makes no guarantees.

Datagram Delivery

The IP datagram is fundamental to the Internet Protocol. A datagram is a type of packet that happens to be sent in a connectionless manner over a network. Every datagram carries enough information to let the network forward the packet to its correct destination;The “best-effort” part means that if something goes wrong and the packet gets lost, corrupted, misdelivered, or in any way fails to reach its intended destination, the network does nothing—it made its best effort, and that is all it has to do. It does not make any attempt to recover from the failure. This is sometimes called an unreliable service.

Best-effort, connectionless service is about the simplest service you could ask for from an internetwork, and this is a great strength. For example, if you provide best effort service over a network that provides a reliable service, then that’s fine—you end up with a best-effort service that just happens to always deliver the packets. If, on the other hand, you had a reliable service model over an unreliable network

Packet Format

Version: Version no. of Internet Protocol used (e.g. IPv4)


Hlen: specifies the length of the header in 32-bit words. When there are no options, which is most of the time, the header is 5 words (20 bytes) long.

TOS: The basic function of TOS is to allow packets to be treated differently based on application needs.


Length: The length includes everything in the datagram – both header and the data, the maximum length is 65,535 bytes.


Identification : The identification field is needed to allow the destination host to determine which datagram a newly arrived fragment belongs to. All the fragments of a datagram contain the same identification value.


Flags: The flags field is of 3-bits, one is unused and two 1-bit fields are DF, MF.

DF means Don’t Fragment , its an order to the router not to fragment the datagram because the receiver is incapable of putting the pieces back to gether again.

MF stands for More Fragments. All fragment except the last one have this bit set. It is needed to know when all fragments of a datagram have arrived.


Offset:The Fragment offset tells where in the current datagram this fragment belongs. All fragments except the last one in a datagram must be a multiple of 8 bytes, the elementary fragment unit. Since 13 bits are provided, there is a maximum of 8192 fragments per datagram, giving a maximum datagram length of 65,536 bytes, one more than the Total length field.


Time to live: The Time to live field is a counter used to limit packet lifetimes. It is supposed to count time in seconds, allowing a maximum lifetime of 255 sec. It must be decremented on each hop and is supposed to be decremented multiple times when queued for a long time in a router. In
practice, it just counts hops. When it hits zero, the packet is discarded and a warning packet is sent back to the source host.
Protocol: When the network layer has assembled a complete datagram, it needs to know what to do with it. The Protocol field tells it which transport process to give it to. TCP is one possibility, but so are UDP and some others.
Checksum: The Header checksum verifies the header only. Such a checksum is useful for detecting errors generated by bad memory words inside a router.

Source address and Destination address: The Source address and Destination address indicate the network number and host number.


Option Description
Security Specifies how secret the datagram is
Strict source routing Gives the complete path to be followed
Loose source routing Gives a list of router not to be missed
Record route Makes each router append its IP address
Timestamp Makes each router append its address and timestamp


IP Addresses

Every host and router on the Internet has an IP address, which encodes its network number and host number. The combination is unique: in principle, no two machines on the Internet have the same IP address. All IP addresses are 32 bits long and are used in the Source address and Destination address fields of IP packets. It is important to note that an IP address does not actually refer to a host. It really refers to a network interface, so if a host is on two networks, it must have two IP addresses. However, in practice, most hosts are on one network and thus have one IP address.

IP addresses were divided into the five categories.This allocation has come to be called classful addressing.


The class A, B, C, and D formats allow for up to 128 networks with 16 million hosts each, 16,384 networks with up to 64K hosts, and 2 million networks (e.g., LANs) with up to 256 hosts each (although a few of these are special). Also supported is multicast, in which a datagram is directed to multiple hosts. Addresses beginning with 1111 are reserved for future use. Over 500,000 networks are now connected to the Internet, and the number grows every year. Network numbers are managed by a nonprofit corporation called ICANN (Internet Corporation for Assigned Names and Numbers) to avoid conflicts.

Datagram Forwarding in IP

IP routers forward datagrams in an internetwork. That forwarding is the process of taking a packet from an input and sending it out on the appropriate output, while routing is the process of building up the tables that allow the correct output for a packet to be determined.

The main points to bear in mind as we discuss the forwarding of IP datagrams are the following:

  • Every IP datagram contains the IP address of the destination host. 
  • The “network part” of an IP address uniquely identifies a single physical network that is part of the larger Internet.
  • All hosts and routers that share the same network part of their address are connected to the same physical network and can thus communicate with each other by sending frames over that network.
  • Every physical network that is part of the Internet has at least one router that,by definition, is also connected to at least one other physical network; this router can exchange packets with hosts or routers on either network.

Forwarding Strategy: 

  • every datagram contains destination's address
  • if directly connected to destination network, then forward to host
  • if not directly connected to destination network, then forward to some router
  • forwarding table maps network number into next hop
  • each host has a default router
  • each router maintains a forwarding table
Datagram forwarding algorithm

if (NetworkNum of destination = NetworkNum of one of my interfaces) then
deliver packet to destination over that interface
else
if (NetworkNum of destination is in my forwarding table) then
deliver packet to NextHop router
else
deliver packet to default router

For a host with only one interface and only a default router in its forwarding table, this simplifies to

if (NetworkNum of destination = my NetworkNum) then
deliver packet to destination directly
else
deliver packet to default router

Wednesday, 6 August 2014

Switching and Forwarding


nA network switch (sometimes known as a switching hub) is a computer networking device that is used to logically connect devices together on a computer network, by using a form of packet switching to forward data to the destination device.

A network switch is a multi-port network bridge that processes and forwards frames at the data link layer (layer 2) of the OSI model. Switches can be designed to route packets in addition to performing packet switching; these switches are commonly known as layer-3 or multilayer switches.


A switch adds the star topology to the point-to-point link,bus (Ethernet), and ring (802.5 and FDDI) topologies.
  • Even though a switch has a fixed number of inputs and outputs, which limits the number of hosts that can be connected to a single switch, large networks can be built by interconnecting a number of switches.
  • We can connect switches to each other and to hosts using point-to-point links, which typically means that we can build networks of large geographic scope.
  • Adding a new host to the network by connecting it to a switch does not necessarily mean that the hosts already connected will get worse performance from the network.
A switch is connected to a set of links and, for each of these links, runs the appropriate data link protocol to communicate with the node at the other end of the link. A switch’s primary job is to receive incoming packets on one of its links and to transmit them on some other link. This function is sometimes referred to as either switching or forwarding.
How does the switch decide which output port to place each packet on? The general answer is that it looks at the header of the packet for an identifier that it uses to make the decision.

There are two common approaches
  • datagram or connectionless approach
  • virtual circuit or connection-oriented approach
A third approach, source routing, is less common than these other two, but it is simple to explain and does have some useful applications. 

Datagrams


The idea behind datagrams is incredibly simple: every packet contains enough information to enable any switch to decide how to get it to its destination. To decide how to forward a packet, a switch consults a forwarding table (sometimes called a routing table)


                                        Datagram forwarding: an example network


Connectionless (datagram) networks have the following characteristics:
  • A host can send a packet anywhere at any time, since any packet that turns up at a switch can be immediately forwarded.This contrasts with most connection-oriented networks, in which some “connection state” needs to be established before the first data packet is sent.
  • When a host sends a packet, it has no way of knowing if the network is capable of delivering it or if the destination host is even up and running.
  • Each packet is forwarded independently of previous packets that might have been sent to the same destination. Thus, two successive packets from host A to host B may follow completely different paths (perhaps because of a change in the forwarding table at some switch in the network).
  • A switch or link failure might not have any serious effect on communication if it is possible to find an alternate route around the failure and to update the forwarding table accordingly.

Virtual Circuit Switching

  • nWidely used technique for packet switching
  • nUses the concept of virtual circuit (VC)
  • nAlso called a connection-oriented model
  • nFirst set up a virtual connection from the source host to the destination host and then send the data

Where host A again wants to send packets to host B.We can think of this as a two-stage process. The first stage is “connection setup.” The second is data transfer.

In the connection setup phase, it is necessary to establish “connection state” in each of the switches between the source and destination hosts. The connection state for a single connection consists of an entry in a “VC table” in each switch through which the connection passes. One entry in the VC table on a single switch contains
  • a virtual circuit identifier (VCI) that uniquely identifies the connection at this switch and that will be carried inside the header of the packets that belong to this connection.
  • an incoming interface on which packets for this VC arrive at the switch.
  • an outgoing interface in which packets for this VC leave the switch.
  • a potentially different VCI that will be used for outgoing packets.

The semantics of one such entry is as follows: If a packet arrives on the designated incoming interface and that packet contains the designated VCI value in its header, then that packet should be sent out the specified outgoing interface with the specified outgoing VCI value first having been placed in its header.


The combination of the VCI of packets as they are received at the switch and the interface on which they are received uniquely identifies the virtual connection. There may of be many virtual connections established in the switch at one time. 

The incoming and outgoing VCI values are generally not the same. The VCI is not a globally significant identifier for the connection; rather, it has significance only on a given link—that is, it has link local scope.
 
Whenever a new connection is created, we need to assign a new VCI for that connection on each link that the connection will traverse. We also need to ensure that the chosen VCI on a given link is not currently in use on that link by some existing connection.

There are two broad classes of approach to establishing connection state. One is to have a network administrator configure the state, in which case the virtual circuit is “permanent.” Of course, it can also be deleted by the administrator, so a permanent virtual circuit (PVC) might best be thought of as a long-lived or administratively configured VC. The next a host can send messages into the network to cause the state to be established. This is called as signalling, and the resulting virtual circuits are said to be switched. The salient characteristic of a switched virtual circuit (SVC) is that a host may set up and delete such a VC dynamically without the involvement of a network administrator. 

Note that an SVC should more accurately be called a “signalled” VC, since it is the use of signalling (not switching) that distinguishes an SVC from a PVC.

There are several things to note about virtual circuit switching:
  • Since host A has to wait for the connection request to reach the far side of the network and return before it can send its first data packet, there is at least one RTT of delay before data is sent.
  • While the connection request contains the full address for host B (which might be quite large, being a global identifier on the network), each data packet contains only a small identifier, which is only unique on one link. Thus, the per-packet overhead caused by the header is reduced relative to the datagram model.
  • If a switch or a link in a connection fails, the connection is broken and a new one will need to be established. Also, the old one needs to be torn down to free up table storage space in the switches.
  • The issue of how a switch decides which link to forward the connection request on has been similarities with the function of a routing algorithm.
For example, an X.25 network—a packet-switched network that uses the connection-oriented model—employs the following three-part strategy:
  1. Buffers are allocated to each virtual circuit when the circuit is initialized.
  2. The sliding window protocol is run between each pair of nodes along the virtual circuit, and this protocol is augmented with flow control to keep the sending node from overrunning the buffers allocated at the receiving node.
  3. The circuit is rejected by a given node if not enough buffers are available at that node when the connection request message is processed.

Source Routing

A third approach to switching that uses neither virtual circuits nor conventional datagrams is known as source routing. The name derives from the fact that all the information about network topology that is required to switch a packet across the network is provided by the source host.

There are various ways to implement source routing. One would be to assign a number to each output of each switch and to place that number in the header of the packet. The switching function is then very simple: For each packet that arrives on an input, the switch would read the port number in the header and transmit the packet on that output. However, since there will in general be more than one switch in the path between the sending and the receiving host, the header for the packet needs to contain enough information to allow every switch in the path to determine which output the packet needs to be placed on.

Three ways to handle headers for source routing: (a) rotation; (b) stripping; (c) pointer. The labels are read right to left.

Tuesday, 5 August 2014

Wireless Lan (802.11)

Wireless Lan(802.11)

Wireless networking is a rapidly evolving technology for connecting computers.the possibilities for building wireless networks are almost endless, ranging from using infrared signals within a single building to constructing a global network from a grid of low-orbit satellites. 

802.11 supports additional features (e.g., time-bounded services, power management, and security mechanisms), but we focus our discussion on its base functionality.

Physical Properties

802.11 was designed to run over three different physical media—two based on spread spectrum radio and one based on diffused infrared.

The idea behind spread spectrum is to spread the signal over a wider frequency band than normal, so as to minimize the impact of interference from other devices. (Spread spectrum was originally designed for military use, so these “other devices” were often attempting to jam the signal.)

A first technique frequency hopping is a spread spectrum technique that involves transmitting the signal over a random sequence of frequencies; that is, first transmitting at one frequency, then a second, then a third, and so on.

A second spread spectrum technique, called direct sequence, achieves the same effect by representing each bit in the frame by multiple bits in the transmitted signal. For each bit the sender wants to transmit, it actually sends the exclusive-OR of that bit and n random bits. As with frequency hopping, the sequence of random bits is generated by a pseudorandom number generator known to both the sender and the receiver. The transmitted values, known as an n-bit chipping code.

The third physical standard for 802.11 is based on infrared signals. The transmission is diffused, meaning that the sender and receiver do not have to be aimed at each other and do not need a clear line of sight. This technology has a range of up to about 10 m and is limited to the inside of buildings only.

Collision Avoidance

The problem is more complicated in a wireless network, Collision detection is not feasible since all nodes are not within the reach of each other. 

                                                          Example wireless network.


Hidden Station
  • Suppose station B is sending data to A. At the same time, station C also has data to send to station A.
  • Since B is not within the range of C, it thinks the medium is free and sends its data to A. Frames from B and C collide at A. Stations B and C are hidden from each other.
Exposed Station
  • Suppose station A is transmitting to station B and station C has some data to send to station D, which can be sent without interfering the transmission from A to B.
  • Station C is exposed to transmission from A and it hears what A is sending and thus refrains from sending, even if the channel is available
Multiple Access with Collision Avoidance (MACA)
  • The idea is for the sender and receiver to exchange short control frames with each other, so that stations nearby can avoid transmitting for the duration of the data frame.
  • The control frames used for collision avoidance is Request to Send (RTS) and Clear to Send (CTS).
  • Any station hearing RTS is close to sender and remains silent long enough for CTS to be transmitted back.
  • Any station hearing CTS remains silent during the upcoming data transmission.
  • The receiver sends an ACK frame to the sender after successfully receiving a frame.
  • If RTS frames from two or more stations collide, then they do not receive CTS. Each node waits for a random amount of time and then tries to send RTS again
Handshake for hidden & exposed station
  • B sends an RTS containing name of sender, receiver & duration of transmission.
  • It reaches A, but not C.
  • The receiver A acknowledges with a CTS message back to the sender B echoing the duration of transmission and other information.
  • The CTS from A is received by both B and C. B starts to transmit data to A.
  • C knows that some hidden station is using the channel and refrains from transmitting.
  • The handshaking messages RTS and CTS does not help in exposed stations because C does not receive CTS from D as it collides with data sent by A.


Distribution System 

  • In wireless network, nodes are mobile and the set of reachable nodes change with time.
  • Mobile nodes are allowed to connect with a wired network infrastructure called access points (AP).
  • Access points are connected to each other by a distribution system (DS) such as ethernet, token ring, etc.
  • Two nodes communicate directly with each other if they are reachable (eg, A and C)
  • Communication between two stations in different APs occurs via two APs (eg, A and E)
                                            Access points connected to a distribution network.

The technique for selecting an AP is called scanning and involves the following four steps:

  1. The node sends a Probe frame.
  2. All APs within reach reply with a Probe Response frame.
  3. The node selects one of the access points and sends that AP an Association Request frame.
  4. The AP replies with an Association Response frame.
The mechanism just described is called active scanning since the node is actively searching for an access point.APs also periodically send a Beacon frame that advertises the capabilities of the access point; these include the transmission rates supported by the AP. This is called passive scanning, and a node can change to this AP based on the Beacon frame simply by sending it an Association Request frame back to the access
point.

Frame Format

802.11 frame format.

  • Control--contains subfields that includes type (management, control or data), subtype (RTS, CTS or ACK) and pair of 1-bit fields ToDS and FromDS.
  • Duration--specifies duration of frame transmission.
  • Addresses--The four address fields depend on value of ToDS and FromDS subfields.
    • When one node is sending directly to another, both DS bits are 0, Addr1 identifies the target node, and Addr2 identifies the source node
    • When both DS bits are set to 1, the message went from a node onto the distribution system, and then from the distribution system to another node. Addr1 contains ultimate destination, Addr2 contains immediate sender, Addr3 contains intermediate destination and Addr4 contains original source.
  • Sequence Control--defines sequence number of the frame to be used in flow control.
  • Payload--can contain a maximum of 2312 bytes and is based on the type and the subtype defined in the Control field
  • CRC--contains CRC-32 error detection sequence.

Fiber Distributed Data Interface (FDDI)

Fiber Distributed Data Interface (FDDI)

The Fiber Distributed Data Interface (FDDI) specifies a 100-Mbps token-passing, dual-ring LAN using fiber-optic cable. FDDI is frequently used as high-speed backbone technology because of its support for high bandwidth and greater distances than copper.

FDDI uses dual-ring architecture with traffic on each ring flowing in opposite directions (called counter-rotating). The dual rings consist of a primary and a secondary ring. During normal operation, the primary ring is used for data transmission, and the secondary ring remains idle. the primary purpose of the dual rings is to provide superior reliability and robustness. 


FDDI Transmission Media 

FDDI uses optical fiber as the primary transmission medium, but it also can run over copper cabling. FDDI over copper is referred to as Copper-Distributed Data Interface (CDDI). Optical fiber has several advantages over copper media. In particular, security, reliability, and performance all are enhanced with optical fiber media because fiber does not emit electrical signals. A physical medium that does emit electrical signals (copper) can be tapped and therefore would permit unauthorized access to the data that is transiting the medium. In addition, fiber is immune to electrical interference from radio frequency interference (RFI) and electromagnetic interference (EMI). Fiber historically has supported much higher bandwidth (throughput potential) than copper, although recent technological advances have made copper capable of transmitting at 100 Mbps. Finally, FDDI allows 2 km between stations using multimode fiber, and even longer distances using a single mode. 

FDDI defines two types of optical fiber: single-mode and multimode. A mode is a ray of light that enters the fiber at a particular angle. Multimode fiber uses LED as the light-generating device, while single-mode fiber generally uses lasers. 

Multimode fiber allows multiple modes of light to propagate through the fiber. Because these modes of light enter the fiber at different angles, they will arrive at the end of the fiber at different times. This characteristic is known as modal dispersion. Modal dispersion limits the bandwidth and distances that can be accomplished using multimode fibers. For this reason, multimode fiber is generally used for connectivity within a building or a relatively geographically contained environment. 

Single-mode fiber allows only one mode of light to propagate through the fiber. Because only a single mode of light is used, modal dispersion is not present with single-mode fiber. Therefore, single-mode fiber is capable of delivering considerably higher performance connectivity over much larger distances, which is why it generally is used for connectivity between buildings and within environments that are more geographically dispersed.


FDDI Specifications 

FDDI specifies the physical and media-access portions of the OSI reference model. FDDI is not actually a single specification, but it is a collection of four separate specifications, each with a specific function. Combined, these specifications have the capability to provide high-speed connectivity between upper-layer protocols such as TCP/IP and IPX, and media such as fiber-optic cabling. 

FDDI's four specifications are the Media Access Control (MAC), Physical Layer Protocol (PHY), Physical-Medium Dependent (PMD), and Station Management (SMT) specifications. The MAC specification defines how the medium is accessed, including frame format, token handling, addressing, algorithms for calculating cyclic redundancy check (CRC) value, and error-recovery mechanisms. The PHY specification defines data encoding/decoding procedures, clocking requirements, and framing, among other functions. The PMD specification defines the characteristics of the transmission medium, including fiber-optic links, power levels, bit-error rates, optical components, and connectors. The SMT specification defines FDDI station configuration, ring configuration, and ring control features, including station insertion and removal, initialization, fault isolation and recovery, scheduling, and statistics collection. 


FDDI Station-Attachment Types

One of the unique characteristics of FDDI is that multiple ways actually exist by which to connect FDDI devices. FDDI defines four types of devices: single-attachment station (SAS), dual-attachment station (DAS), single-attached concentrator (SAC), and dual-attached concentrator (DAC). 

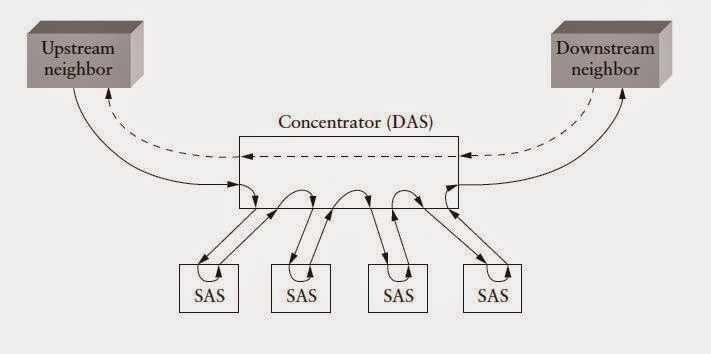
An SAS attaches to only one ring (the primary) through a concentrator. One of the primary advantages of connecting devices with SAS attachments is that the devices will not have any effect on the FDDI ring if they are disconnected or powered off.. 

Each FDDI DAS has two ports, designated A and B. These ports connect the DAS to the dual FDDI ring. Therefore, each port provides a connection for both the primary and the secondary rings. As you will see in the next section, devices using DAS connections will affect the rings if they are disconnected or powered off. 

An FDDI concentrator (also called a dual-attachment concentrator [DAC]) is the building block of an FDDI network. It attaches directly to both the primary and secondary rings and ensures that the failure or power-down of any SAS does not bring down the ring. This is particularly useful when PCs, or similar devices that are frequently powered on and off, connect to the ring. 


                                                      SASs connected to a concentrator.

FDDI Fault Tolerance

FDDI provides a number of fault-tolerant features. In particular, FDDI's dual-ring environment, the implementation of the optical bypass switch, and dual-homing support make FDDI a resilient media technology.


Dual Ring

FDDI's primary fault-tolerant feature is the dual ring. If a station on the dual ring fails or is powered down, or if the cable is damaged, the dual ring is automatically wrapped (doubled back onto itself) into a single ring. When the ring is wrapped, the dual-ring topology becomes a single-ring topology. Data continues to be transmitted on the FDDI ring without performance impact during the wrap condition. 

When a single station fails, as shown in Figure 8-6, devices on either side of the failed (or powered-down) station wrap, forming a single ring. Network operation continues for the remaining stations on the ring. When a cable failure occurs, as shown in the above figure, devices on either side of the cable fault wrap. Network operation continues for all stations. 

It should be noted that FDDI truly provides fault tolerance against a single failure only. When two or more failures occur, the FDDI ring segments into two or more independent rings that are incapable of communicating with each other.
                                  Dual-fiber ring: (a) normal operation; (b) failure of the primary ring.

Dual Homing

Critical devices, such as routers or mainframe hosts, can use a fault-tolerant technique called dual homing to provide additional redundancy and to help guarantee operation. In dual-homing situations, the critical device is attached to two concentrators. 

One pair of concentrator links is declared the active link; the other pair is declared passive. The passive link stays in backup mode until the primary link (or the concentrator to which it is attached) is determined to have failed. When this occurs, the passive link automatically activates. 


FDDI Frame Fields

The following descriptions summarize the FDDI data frame and token fields illustrated in the above figure.
  • Preamble - Gives a unique sequence that prepares each station for an upcoming frame.
  • Start delimiter - Indicates the beginning of a frame by employing a signaling pattern that differentiates it from the rest of the frame.
  • Frame control - Indicates the size of the address fields and whether the frame contains asynchronous or synchronous data, among other control information.
  • Destination address - Contains a unicast (singular), multicast (group), or broadcast (every station) address. As with Ethernet and Token Ring addresses, FDDI destination addresses are 6 bytes long.
  • Source address - Identifies the single station that sent the frame. As with Ethernet and Token Ring addresses, FDDI source addresses are 6 bytes long.
  • Data - Contains either information destined for an upper-layer protocol or control information.
  • Frame check sequence (FCS) - Is filed by the source station with a calculated cyclic redundancy check value dependent on frame contents (as with Token Ring and Ethernet). The destination address recalculates the value to determine whether the frame was damaged in transit. If so, the frame is discarded.
  • End delimiter - Contains unique symbols; cannot be data symbols that indicate the end of the frame.
  • Frame status - Allows the source station to determine whether an error occurred; identifies whether the frame was recognized and copied by a receiving station.